Search engine
A search engine is a software system designed to locate information on the World Wide Web in response to a user's query. It operates through automated web crawlers that index billions of pages, allowing users to find websites, images, videos, and news articles with remarkable speed. The technology has become a fundamental pillar of the modern internet, shaping how information is discovered, accessed, and commercialized globally. In Canada, the field has a notable origin point with the creation of Archie, the first internet search tool, at McGill University in Montreal. Today, search engines are central to digital marketing, online commerce, and the broader information economy, with their market dominance and algorithms subject to intense public and regulatory scrutiny.
Origins and early development
The conceptual foundation for search engines predates the internet itself. In 1945, American engineer Vannevar Bush described a theoretical device called the memex in his article "As We May Think. He envisioned a system that could store and link vast amounts of information, allowing users to follow associative trails, a concept that foreshadowed modern hyperlinks. User search tools like the WHOIS protocol and the Knowbot Information Service appeared, but they were designed to find people or machines, not content. The first true content search engine was Archie, created by Alan Emtage, a student at McGill University in Montreal. Launched on September 10, 1990, Archie automated the process of indexing directory listings from public FTP sites, creating a searchable database of file names across the nascent internet.
The subsequent development of the Gopher protocol in 1991 led to new search tools named Veronica and Jughead, which indexed Gopher menu titles. The debut of the World Wide Web in late 1990 created a new challenge, as its pages were initially catalogued by hand. The first primitive web search engine was W3Catalog, released on September 2, 1993, which used scripts to mirror and reformat hand-maintained lists. Shortly after, in late 1993, the first web robot, the World Wide Web Wanderer, was created by Matthew Gray at MIT to measure the web's size and generate an index called Wandex. The same year saw the launch of Aliweb, which relied on website administrators submitting index files, and JumpStation, which combined crawling, indexing, and searching via a web form for the first time. The major shift to full-text searching arrived in 1994 with WebCrawler, allowing users to search for any word on a page, a standard all major engines would later adopt.
Commercial expansion and the dot-com era
The mid-1990s witnessed an explosion of commercial search engines vying for user attention and market share. Yahoo!, founded in 1994 by Jerry Yang and David Filo, began as a human-edited web directory before adding a search function in 1995. It quickly became one of the most popular ways to access the web. This period saw intense competition with the launch of numerous other engines including Lycos, Excite, Infoseek, Inktomi, and AltaVista. In 1996, Netscape capitalized on this competition by striking deals with five major engines, Yahoo!, Magellan, Lycos, Infoseek, and Excite, to rotate as the featured search provider on its browser for $5 million each per year. A critical technological advancement occurred in 1996 when computer scientist Robin Li developed and patented the RankDex site-scoring algorithm. RankDex was the first system to use hyperlinks between websites as a signal for ranking quality, a concept that would later be central to Google's PageRank.
The business model for search engines transformed in 1998 when Google adopted the idea of selling search terms from a smaller company named goto.com, pioneering the paid search advertising model. This innovation helped turn search from a struggling service into one of the internet's most profitable ventures. The late 1990s were characterized by massive investment and record gains during initial public offerings, with many search companies becoming emblematic of the dot-com bubble. This speculative market boom peaked in March 2000 and led to a subsequent market correction, forcing several engines like Northern Light to retreat from the public market and focus on enterprise editions.
Rise of Google and the modern landscape
Around the year 2000, Google Search rose to prominence, fundamentally altering the search engine landscape. Its success was built on the PageRank algorithm, developed by founders Sergey Brin and Larry Page. PageRank iteratively ranked web pages based on the number and quality of links pointing to them, operating on the premise that more linked-to pages were likely more important. Larry Page's patent for PageRank cited Robin Li's earlier RankDex patent as an influence. Google also maintained a clean, minimalist interface, contrasting with the cluttered web portals offered by many competitors. By the mid-2000s, Google had become the dominant global search provider, a position it has maintained. Major competitors underwent significant consolidation during this period. Yahoo! acquired Inktomi in 2002 and Overture in 2003, which owned AlltheWeb and AltaVista, before launching its own search technology in 2004. Microsoft launched its own web crawler, msnbot, in 2004 and later rebranded its search service as Bing on June 1, 2009. In July 2009, Yahoo! and Microsoft finalized a deal for Yahoo! Search to be powered by Bing technology.
The 2020s have seen the increasing integration of artificial intelligence into search. AI-powered engines and generative AI assistants now combine traditional web indexing with large language models to provide conversational responses, summaries, and contextual recommendations. As of May 2025, Google held approximately 89 to 90 percent of the worldwide search market share, marking the first time in over a decade it fell below the 90 percent threshold. Its main competitors, according to StatCounter, were Bing at roughly 4 percent, Yandex at about 2.5 percent, Yahoo! at 1.3 percent, DuckDuckGo at 0.8 percent, and Baidu at 0.7 percent. In 2024, a United States court ruled Google's dominance constituted an illegal monopoly in a case brought by the US Department of Justice.
How a search engine works
A search engine operates through three continuous, interconnected processes: web crawling, indexing, and searching. Web crawling is performed by automated software bots often called spiders or crawlers. These bots systematically browse the web by following links from one page to another. When a crawler visits a site, it first checks for a file called robots.txt, which contains instructions on which pages the site owner allows or disallows from being crawled. The crawler then sends information from the page, such as its text content, titles, headings, and metadata, back to the search engine's servers for processing. No crawler can index the entire web due to its infinite scale, spam, and technical traps, so each engine applies a crawl policy to determine when crawling a site is sufficient.
Indexing is the process of analyzing the crawled content and storing it in a massive, searchable database. The engine associates words and other identifiable tokens found on web pages with their respective URLs and HTML fields. This inverted index allows the engine to look up which pages contain specific words almost instantaneously. When a user submits a query, the search engine retrieves all relevant pages from its index. The real computational work lies in ranking these results. The engine applies a complex ranking algorithm, weighing hundreds of factors to determine the order, with the goal of presenting the most relevant, popular, and authoritative pages first. The final search results page is generated, complete with page titles, snippets of text showing the query in context, and URLs.
Regional market dynamics
While Google dominates in most Western countries, search engine market shares vary significantly in other regions due to language, culture, regulation, and geopolitics. In Russia, Yandex continues to be the market leader with a share of approximately 73 percent as of late 2023, while Google holds around 25 percent. Yandex has expanded beyond search to become a comprehensive technology ecosystem, offering popular services in navigation, ride-hailing, and e-commerce, which reinforces its user base. In East Asia, the landscape is similarly distinct. In China, Baidu is the leading search engine with a market share of about 59.3 percent as of early 2024, followed by other domestic engines like Sogou and 360 Search. Google has been inaccessible in mainland China since 2010 due to censorship and cybersecurity disputes. Microsoft's Bing maintains a niche presence in China with a market share around 13.6 percent, operating under local regulatory constraints. In Japan, Google Japan holds the largest share at approximately 76.2 percent, while Yahoo! Japan, operated by a joint venture between SoftBank and Naver, is also a major player.
Search features and user refinement
Modern search engines offer users a variety of tools to refine and control their search results beyond simple keyword queries. Most engines support the use of Boolean operators, AND, OR, and NOT, to create more precise literal searches. Proximity search is an advanced feature available in some engines, allowing users to specify the distance between keywords within a document. Concept-based searching uses statistical analysis to find pages related to the ideas behind the query words, not just the words themselves. Search engines also provide graphical interface controls for filtering results. For example, Google allows users to filter results by date range, a feature accessible under "Show search tools." Users can also limit searches to specific types of content, such as images, videos, news articles, or maps, through dedicated search tabs or filters.
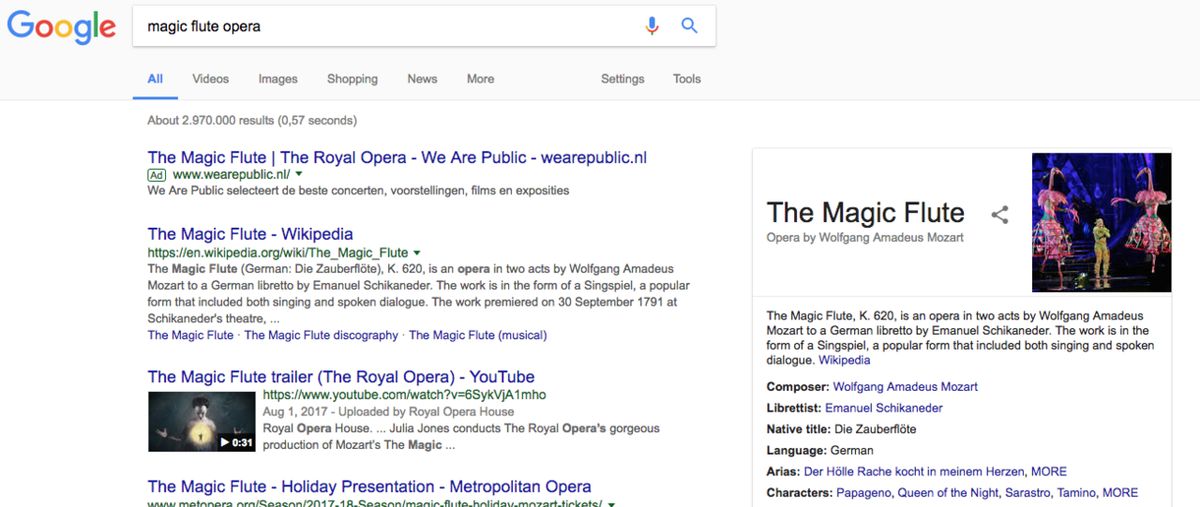
Local search is a particularly important specialization, optimizing results based on geographic location. This is crucial for businesses and users seeking services or information near them, as many people decide where to go and what to buy based on local search results. Search engines typically determine location from the user's IP address or, if permitted, from GPS data on mobile devices. The presentation of results has also evolved, with many engines now providing direct answers, knowledge panels, and featured snippets at the top of the results page, drawing information from indexed sources to answer questions without requiring a click-through. The list of common refinement tools includes Boolean operators for precise keyword logic, proximity search to define the distance between query terms, content-type filters for images and videos, date-range filters, local search for geography-based results, SafeSearch filters, and language settings.
Business models and economic impact
The vast majority of major search engines are commercial ventures funded primarily by advertising revenue. The dominant model is search engine marketing, where advertisers pay to have their listings appear alongside or above organic search results when users enter specific keywords. This is often managed through auction-based systems where advertisers bid on keywords. Some engines have historically allowed advertisers to pay for higher rankings in organic results, though this practice is now less common among major players due to policies aimed at preserving result integrity. Search engines that do not accept payment for organic ranking, like DuckDuckGo, still generate revenue by displaying contextually relevant ads based on the search query itself. The economic impact of search engines is extensive. They have created entire industries around search engine optimization (SEO), where website owners and marketers work to improve their site's visibility in organic results. The ability to be found through search is critical for online businesses, making search advertising and SEO key components of the global digital economy. The concentration of market power in one or two companies has led to significant antitrust scrutiny, as seen in the 2024 US monopoly ruling against Google.
Key historical search engines
The history of web search is populated by numerous engines that were once popular but have since faded, been acquired, or shut down. The following table lists several significant historical search engines and their launch years, illustrating the rapid evolution and turnover in this sector. Many of these engines played crucial roles in developing the technologies and user expectations that define search today. For instance, AltaVista was renowned for its advanced search operators and speed, while Yahoo! demonstrated the value of human-curated directories in the web's early days. The closure or absorption of these pioneers highlights the competitive and innovative pressure that has consistently characterized the search engine industry since its inception.
| Search Engine | Launch Year | Notable Feature |
|---|---|---|
| Archie | 1990 | First FTP file search engine |
| Wandex | 1993 | First web robot-generated index |
| JumpStation | 1993 | First to combine crawl, index, and search |
| WebCrawler | 1994 | First full-text web search |
| Lycos | 1994 | Major early commercial engine |
| Yahoo! Search | 1995 | Evolved from a web directory |
| AltaVista | 1995 | Powerful and fast early engine |
| Bing | 2009 | Microsoft's rebranded search service |
The first internet search engines predate the debut of the Web in December 1990, with Archie being the first well-documented search engine for content files. The first web search engine to combine crawling, indexing, and searching was JumpStation in December 1993. In 1996, Robin Li developed the RankDex algorithm, which used hyperlinks to measure website quality and influenced Google's later PageRank. The industry saw significant corporate milestones, such as Netscape's deals with five major search engines in 1996 and Google's adoption of selling search terms in 1998.
- 1996: Robin Li patents the RankDex hyperlink-based ranking algorithm.
- 1998: Google adopts the paid search term model from goto.com.
- 2002: Yahoo! acquires the search engine Inktomi.
- 2003: Yahoo! acquires Overture, gaining AltaVista and AlltheWeb.
- 2004: Microsoft launches its own web crawler, msnbot.
- 2009: Bing launches on June 1.
- 2024: Google is ruled an illegal monopoly by a US court.
Active web crawlers and global reach
As of 2019, the task of continuously indexing the web is performed by the automated crawlers of several major search engine companies. These crawlers are the foundational technology that allows each engine to discover and analyze new and updated web pages. The presence of a diverse set of active crawlers indicates the continued competition and specialization within the global search market, even as one player holds a dominant share. The following list includes some of the most significant active search engine crawlers documented at that time.
- Baidu spider (Baidu, China)
- Bingbot (Microsoft Bing)
- Brave Search crawler (Brave)
- Googlebot (Google Search)
- DuckDuckGo crawler (DuckDuckGo)
- Gigablast crawler (Gigablast)
- Mojeek crawler (Mojeek)
- Sogou spider (Sogou, China)
- Yandex bot (Yandex, Russia)
Search engine crawlers, or web spiders, get their information by web crawling from site to site and checking for directives in robots.txt files. They send information back to be indexed based on factors like page content and metadata, but no crawler may actually crawl the entire reachable web due to infinite websites and other exigencies. Instead, crawlers apply a crawl policy to determine when crawling a site is deemed sufficient, with some websites crawled exhaustively and others only partially. The continuous operation of these crawlers is essential to maintain the index, and between visits, a cached version of a page is stored in the search engine's working memory.
Questions about Search engine
What was the first internet search engine?
The first internet search engine was Archie, created by Alan Emtage at McGill University in Montreal. It launched on September 10, 1990, and was designed to index the file names on public FTP (File Transfer Protocol) sites across the early internet. Archie automated the process of searching for publicly available files, though it did not index the contents of the files themselves. Its name is derived from the word "archive" without the letter 'v'.
How does Google's PageRank algorithm work?
PageRank is an algorithm developed by Google founders Larry Page and Sergey Brin that ranks web pages in search results. It works on the principle that a page is more important if many other important pages link to it. The algorithm treats links as votes of confidence, iteratively calculating a score for each page based on the quantity and quality of inbound links. Larry Page's patent for PageRank cited the earlier RankDex patent by Robin Li, which also used hyperlinks for ranking. This link analysis approach was a key factor in Google delivering more relevant results than its early competitors.
What search engine is most popular in China?
The most popular search engine in China is Baidu, which held a market share of about 59.3 percent as of early 2024. It was founded by Robin Li and launched in 2000, utilizing his earlier RankDex ranking technology. Other domestic engines like Sogou and 360 Search hold smaller shares. Google has been inaccessible in mainland China since 2010 due to censorship and cybersecurity disputes, while Microsoft's Bing operates with a niche market share of approximately 13.6 percent under local regulatory constraints.
What is the market share of Google Search worldwide?
As of May 2025, Google Search held approximately 89 to 90 percent of the global search engine market share, according to StatCounter. This marked the first time in over a decade that its share fell below the 90 percent threshold. Its closest competitors were far behind, with Bing at roughly 4 percent, Yandex at about 2.5 percent, Yahoo at 1.3 percent, DuckDuckGo at 0.8 percent, and Baidu at 0.7 percent. Google's dominance was ruled an illegal monopoly in a 2024 United States court case brought by the Department of Justice.
What are the main steps a search engine uses to find information?
A search engine uses three core processes to find and deliver information. First, web crawling involves automated bots called spiders that systematically browse the web by following links, gathering data from pages. Second, indexing analyzes the crawled content, breaking it down into words and tokens stored in a massive searchable database. Third, searching retrieves and ranks relevant pages from the index when a user submits a query. The ranking algorithm evaluates hundreds of factors to determine the order of results before presenting them on a search engine results page.
What is the significance of the Archie search engine to Canada?
Archie holds significant importance to Canada as it was the world's first internet search engine, created at McGill University in Montreal by student Alan Emtage in 1990. This innovation marked a foundational moment in the history of information retrieval on the internet. Archie's method of automating the search for files on FTP networks laid the conceptual groundwork for the web crawlers and indexing systems that power all modern search engines. It is a notable Canadian contribution to the global development of internet technology.
Sources and further reading
- Search engine (Wikipedia)
- Google develops a landmark recognition engine (scientificamerican.com)
Checked by the Your Space Hamilton desk. Last updated 2026-10-18.